In the last post I built a small bridge: label a ProPresenter slide with an OBS scene name, and OBS switches to that camera the moment the slide goes live. It worked the day I built it. I set it to start automatically and without a window when Windows logs in, and I left it alone.
The next day it was dead. Not crashed — dead while looking perfectly alive.
My setup is the same as before: ProPresenter 21.3.1 and OBS 30.0.2 (obs-websocket 5.3.4) on one Windows 11 PC, with the bridge written in Python 3.12. Everything below happened on 28 September 2026.
If you run any automation unattended, the conclusions matter more than the details, so here they are up front. An automation that stops should stop loudly — mine stopped quietly and left a log line that made it sound busy. And once I fixed that, it became too eager and started crashing OBS, which turned out to be the more interesting half of the day.
What I found
The bridge writes what it does to a log file. The last line was this:
10:04 OBS connection problem, waiting to reconnect [WinError 10053]WinError 10053 means the connection was aborted by software on this machine. That is what you get when OBS closes. Nothing suspicious about the error itself.
What was suspicious was that nothing came after it. I had restarted OBS several times that morning. There should have been a “reconnected” line somewhere. There wasn’t. The log simply ended at 10:04.
Two wrong guesses
First guess: the OBS WebSocket password changed. This was the plausible one. A wrong password means no connection, and no connection could explain a log that just stops. I checked. The password had never been changed. Dead end.
Second guess: the program hung. If Python had frozen somewhere, the silent log is explained. This was also wrong, as the next step showed.
There is a lesson buried in those two misses. A log that stops does not mean the program stopped. It can just as easily mean the code never reached the line that writes the log. Those are completely different failures, and guessing between them costs you time.
The diagnosis order that actually worked
I stopped guessing and measured, in order. These ran in PowerShell on the broadcast-booth Windows PC — not on my desktop.
Step 1: is the process actually running? Measure cumulative CPU time twice. A frozen process does not accumulate CPU time. A looping one does.
(Get-Process pythonw).CPU     # write it down
# wait 10 seconds
(Get-Process pythonw).CPU     # has it gone up?
It had gone up. A little, steadily. The polling loop that runs every 0.25 seconds was alive and turning.
Step 2: is it still talking to ProPresenter? Count the connection remnants. The bridge queries the ProPresenter API four times a second. Each finished connection lingers briefly in TIME_WAIT.
(Get-NetTCPConnection -RemotePort <ProPresenter port> -State TimeWait).CountSeveral hundred. It was querying away, right that second.
So the conclusion inverted. The program had not stopped. It was reading ProPresenter continuously. It simply never reconnected to OBS. Alive, busy, and not doing its job.
The real cause: reconnection was trapped inside the slide-change branch
Process alive, ProPresenter being read, OBS never reconnecting. That leaves control flow. Here is the shape of what I found:
while True:
    key, label = live_slide()
    if key == last_key:          # slide hasn't changed
        time.sleep(0.25)
        continue                 # ← back to the top from here
    last_key = key
    if cl is None:               # no connection? connect here
        cl = connect_obs()       # ← only reachable when a slide changes
    ...
There it is. The reconnect lives inside the “a slide changed” branch.
When the slide does not change, the loop hits continue and goes back up. It never reaches the line that checks the connection. OBS closed at 10:04, the connection died, and after that nobody advanced a slide. There was never an opportunity to reconnect.
How many times I restarted OBS was irrelevant. The bridge wasn’t watching OBS. It was watching the slides, and the slides were sitting still.
The side effect I found in the same code
One more thing came out of those lines, and this one shows up on Sunday far more often.
A slide whose switch failed was still being marked as handled. Look at the order above: last_key = key runs before the connect-and-switch attempt. So if the switch raises an exception, the slide is already recorded as processed.
Which produces this symptom: restart OBS, let the bridge reconnect, and the first slide you advance does not switch the camera. From the second one on, everything is fine.
On a Sunday morning you experience that as “the bridge is a bit flaky.” It is not flakiness. It is one line in the wrong place.
Confirming it
If the diagnosis is right, advancing a single slide should fix it on the spot. I brought up a test song with labeled slides and clicked once.
The bridge reconnected immediately and the scene switched as labeled. Exactly as predicted — the slide changed, so the code finally fell through to the reconnect.
Fix one: pull reconnection out of the slide-change branch
Three changes.
- Reconnect independently of the slides. If there is no connection, try every 5 seconds. Do not wait for a slide change.
- Retry a slide whose switch failed. Mark it handled only after a successful switch.
- Check liveness every 30 seconds while connected, and log it. No more dying quietly.
last_try = last_ping = 0.0
while True:
    now = time.monotonic()
    if cl is None and now - last_try > 5:        # 1. reconnect, slides or no slides
        last_try = now
        cl = connect_obs()
    elif cl and now - last_ping > 30:            # 3. liveness check while connected
        last_ping = now
        if not alive(cl):
            log("OBS not responding - dropping the connection and reconnecting")
            cl = None

    key, label = live_slide()
    if key != last_key and cl:
        try:
            switch(cl, label)
            last_key = key                       # 2. mark handled only on success
        except Exception as e:
            log(f"switch failed, will retry this slide: {e}")
            cl = None                            #    leave last_key alone
    time.sleep(0.25)
Nothing new was added. Connection management moved out of the slide-change branch, and the “handled” marker moved after the success. It is a fix of ordering, not of features.
A detour: editing the file is not the same as running the edit
I got caught by this once in the middle of it. The file was fixed, the bridge had not been restarted, and what was running was still the old code.
Obvious when stated, easy to miss in practice. A Python script reads its file when it starts. The process already running still holds the old version. This bites hardest with something like this bridge, which launches automatically with no window — you get the satisfying feeling of having fixed it, and there is no window in front of you to remind you otherwise.
Same lesson, new face. A living process was not a working process; a fixed file is not running code.
After a restart it behaved exactly as intended: “OBS connected” appeared in the log with no slide advance at all.
Act two: the fix started crashing OBS
Reconnection was solved. But now OBS began vanishing seconds after launch. The window simply disappeared. No crash report. Nothing in the Windows event log. It happened three times.
I had fixed an automation that stopped silently and produced an OBS that disappeared silently.
Diagnosis: line the logs up by time
With no crash record, the only evidence left is timing. I put the bridge log and the OBS log side by side in time order. All three incidents had the same sequence:
bridge: OBS connected
  +1s   OBS: starting capture device
        OBS: (gone)
One of them came right after the bridge’s scene-list request got back 207, “OBS not ready.” That was the deciding clue.
The bridge was connecting and issuing requests while OBS was still starting up — at the exact moment OBS is claiming capture devices. I was knocking on the door while someone was carrying furniture through it.
And fix one is what created this. Before, the bridge only connected when a slide changed, so it rarely hit OBS mid-startup. Once it knocked politely every five seconds, hitting the startup window became guaranteed.
Ruling out the other suspect first
There was a confounder. At the same time, I had added a render delay filter to a camera source — part of syncing a wireless camera. That change overlaps exactly with when OBS started crashing.
But walking back through it: with the filter in place and the old bridge running (connect only on slide change), OBS stayed up for minutes at a stretch. If the filter were the cause, it would have crashed then too. The filter is out.
If you changed two things at once, revert one to separate them. Overlapping in time is not the same as causing.
Confirming it: stop the bridge, start OBS alone
The cleanest experiment is to remove the suspect. I stopped the bridge and launched OBS by itself.
Rock solid. No crash. That settled it.
Fix two: give the knocking some manners
Four changes, all of them about when to knock rather than whether.
- Stay silent for 10 seconds after connecting. Let OBS finish getting its footing.
- Treat “not ready” as “hold on,” not as a refusal. On a 207, keep the connection and ask again in 3 seconds.
- Raise the reconnect interval from 5 to 15 seconds. Be less eager.
- Disconnect properly instead of abandoning the socket.
One more, outside the bridge. My OBS restart script waited 20 seconds for OBS to exit. Measured, OBS takes 22 to 23 seconds to shut down fully. Wait only 20 and you launch the new OBS while the old one is still alive — two OBS instances fighting over the same capture devices. That alone is enough to cause the failure I was chasing. The wait is now 40 seconds.
Results
- OBS stayed up past 60 seconds, where before it vanished within moments of launch.
- The bridge reconnected 15 seconds after a disconnect, with no slide advance. Fix one’s purpose survived intact.
The full label-switching run passed too. I tested it on the second revision, right after booting the booth PC unattended. Every label in my test set — cameras 1, 2, 3 and 4 — switched the OBS scene. I clicked back and forth through the slides repeatedly and it followed every time, with no disconnects and no crashes.
From slide change to scene change: 0.0 to 0.4 seconds.
Worth saying how that was measured, because it wasn’t by eye in the booth. From my office machine I polled ProPresenter’s live slide every 0.3 seconds and subscribed to OBS’s scene-change events, then lined the two timestamps up.
One thing I did not verify: whether the bridge returns to the previous scene after a labeled run ends. That is rule two from the last post, and this test didn’t cover it. Next on the list.
A bonus failure — the tool that was watching also stopped quietly. My recording tool had a 5-second timeout waiting for events, hit it, and shut itself down mid-test. I removed the limit and restarted it. The thing I built to watch for silent failures failed silently, in the same way. This article’s subject came all the way around.
A footnote on OBS safe mode
OBS asks “Run in safe mode?” after an abnormal shutdown. When OBS vanishes the way mine did, you get that prompt on every launch afterward — including, eventually, right before a service.
There is a launch flag that skips the check (--disable-shutdown-check). But using it before you find the cause is disconnecting a warning light. That prompt means “last time I went down badly,” and in this diagnosis the prompt itself was a clue.
Fix the cause first, then use the flag only to survive reboots. Order matters.
What I took away
An automation that stops should stop loudly.
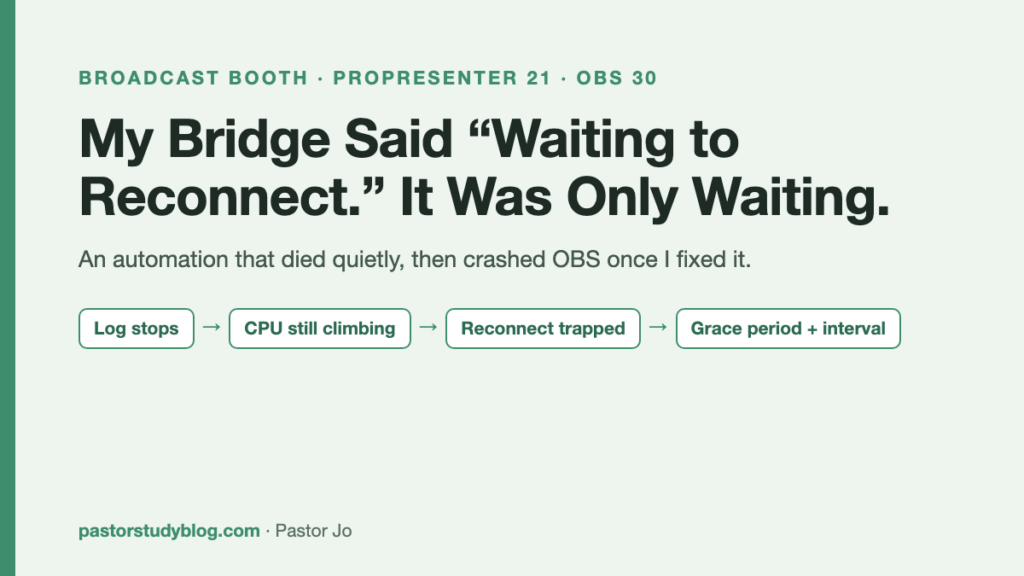
The worst part of this failure was the log line itself: waiting to reconnect. Read it and you assume something is being attempted. Nothing was. It waited and never tried. When your log describes work the code does not do, the log is lying to you — and you will trust it, because you wrote it.
A living process is not a working process. If it is in Task Manager, it feels like it is running. This one was running, burning CPU, reading ProPresenter four times a second, and failing at its only job.
Fixes create their own failures. I repaired an automation that stopped quietly and got one that was too eager. After a fix, don’t only check that the old symptom is gone — check what the fix newly touches.
Don’t knock on a program that is still starting. A reconnect loop needs two things together: a grace period right after connecting, and an interval that keeps it from hammering. One without the other produces exactly what I got.
“Not ready” is not a refusal. Drop the connection on that response and you get an endless connect-disconnect cycle. Wait and ask again.
Don’t change two things at once. If you must, revert one to separate them. I suspected the render delay filter; it only overlapped in time.
Check in this order:
- The last log line — when did it stop, and what does it claim?
- Process liveness — measure cumulative CPU twice; is it climbing?
- Control flow — is there a path that actually reaches the line you expected to see?
And after a fix there is one more step: did you restart it? Editing the file and running the edited code are two different events.
Keep that order and you narrow it in one pass. I skipped it, started with the password, and paid for two dead ends.
A footnote on how this got diagnosed
I did not walk down to the booth for any of this. The AI session I keep pinned as “headquarters” on my desk handed the job to the AI session on the booth PC, which read the log and the code read-only, with the password line masked.
Next
This post is a follow-up to switching OBS cameras from ProPresenter slide labels. Still on my list:
- Verify the return-to-previous-scene behavior after a labeled run ends — the one thing this test missed
- Run a real Sunday on the fixed bridge and confirm the first slide after a restart switches
- Verify the 30-second liveness lines actually appear in the log